

Build, Buy, or Both: How to Choose your AI Pentesting Path


An enterprise customer set out to build and run its own AI agents to pentest its attack surface. It didn’t take long for the company to discover the job was a lot more complicated, costly, and time-consuming than they had expected.
After a few months of trying it on its own, the company signed on with RunSybil for continuous AI pentesting.
This customer wasn’t alone in wondering why they should hire an AI cybersecurity vendor when they could just use Claude Code or Codex to build their own agents or simply prompt AI to find vulnerabilities, and handle it all on their own. Why not? Sounds doable and cheaper.
For some organizations, parts of it can be. Plenty of security teams have the talent to build a few agents in-house, and some of them should. The hard part isn’t building one piece. It’s building a system that is scalable and consistently effective across every piece, and then keeping it that way as models change and attackers get their hands on the same, or better, models.
We’re not saying don’t build your own agents. Not at all. We’re saying they shouldn’t be your only line of defense. You also should go in knowing what the full job looks like.
In this blog post, we’ll walk through five areas to weigh before you decide: the harness, multi-agent orchestration, validation, ongoing research and evaluations, and the resources it takes to keep it all running. We’ll also look at how one company made the call, and how Sybil compares to Mythos.
1. The Harness
A better model makes the reasoning better, but on its own, a model can’t test anything. The harness is what lets it take action: running tools, sending requests, and deciding what to try next. It’s the infrastructure that decides what the model sees, what it can touch, what it’s allowed to do, and how its work gets checked and stored so it can test an application safely and thoroughly.
Our harness, and the system around it, is one of the things that sets Sybil apart. Sybil finds 1.5 times as many vulnerabilities as some frontier model and harness configurations like Opus 5.5 in Claude Code.
Depth is a big part of that. Coding agents find the headline bugs fast, but then they call the job done. Sybil moves endpoint by endpoint through the hidden edge cases: malformed IDs, out-of-order state actions, and replayed or raced requests. In one benchmark, Sybil caught an API that ignored its own idempotency key, allowing identical requests to each create a separate transaction. None of the 24 coding-agent runs we benchmarked caught it.
A strong harness also has to keep testing safe. Sybil tests with authenticated user roles, keeps every request inside your authorized scope, and offers automated scope recommendations so your team isn’t defining the boundaries of every evaluation by hand.
2. Multi-Agent Orchestration
A handful of homegrown agents can each find vulnerabilities, but they tend to work in isolation. In a typical engagement, one agent might uncover a flaw that exposes sensitive files, while another, testing a nearby feature, notices that the application relies on something stored in those same files. Neither finding sets off alarm bells on its own. Together, though, they can form a critical exploit chain that lets an attacker escalate to admin access.
Sybil connects those dots. When you have multiple agents working together, these two seemingly unrelated findings become one confirmed, reproducible path from an unauthenticated observer to total system compromise.
Now multiply that across hundreds or thousands of coordinated agents working the same engagement. Every additional agent covers more of the attack surface, and every finding becomes a potential link in a chain another agent can build on. That’s what happens when testing agents work at scale and talk to each other.
- Modern app risk stems from how small findings chain together. Sybil’s multi-agent orchestration is built for one goal: catching specific findings that chain into serious, exploitable risk.
- During each engagement, Sybil deploys an average of 2,700 coordinated agents in a layered hierarchy. They share real-time context just like an elite, focused team of human pentesters.
- Because Sybil’s agents share context in real time, they can connect low-priority findings across an app to reveal critical, chainable exploits.
From One Engineer to 6,100 Agents
3. Validation
Finding a possible vulnerability is not the same as proving it. General-purpose agents might look cheap until an organization’s engineers spend weeks sorting through noise. Fewer false positives mean cost savings.
Sybil sorts what it finds into two buckets. Findings are confirmed, high-impact vulnerabilities, each with proof of exploitation against your running application. Observations are valid, lower-impact issues, each with an explanation of why it was rated lower-impact. Customers use Findings for a noiseless, high-priority view of what needs fixing now, and Observations for complete visibility into everything Sybil sees.
Before a Finding reaches you, a separate check re-runs the exploit to confirm it’s real. Sybil also filters out duplicates and non-exploitable bugs, and every Finding comes with remediation guidance so engineers can fix it right away.
That isn’t something you get from Codex or Claude Code on their own. Point a coding agent at an application and you’ll get back a list of possible issues. It isn’t built to prove exploitation against your live app, independently re-run each exploit, or separate what needs fixing today from what can safely wait. That work falls back on your team.
4. Ongoing Research and Evaluations
This is the consideration most often left out of the build plan. Frontier models change every few months, and each release changes what works: which prompts, which tools, and which harness designs get the best results. A system tuned for last quarter’s model can quietly lose ground on the next one.
Attackers are on the same curve. As they get access to more advanced models, the bar for what your testing needs to catch keeps moving up.
Staying effective means evaluating constantly: benchmarking new models as they drop, measuring how many real vulnerabilities each one finds and how much noise it creates, catching regressions, and folding what works back into the harness. Sybil is built around that work, which is why it can use whichever model is right for the job.
How Sybil Compares to Mythos
Anthropic’s Mythos is a model. On its own, it can’t test your application. Sybil is the system that does, using whichever model is best for the job.
The real question isn’t whether you can get Mythos access. It’s whether you can maximize its ability to find real issues while minimizing noise and side effects, and keep up with new model releases and technique improvements.
Most CISOs can’t use frontier models at their full offensive security strength. Access to Project Glasswing and the AI labs’ advanced cybersecurity programs is limited to a small group of vetted organizations. Sybil delivers that level of performance, or better, by pairing a premium harness and the system built around it for a solution CISOs can actually use.
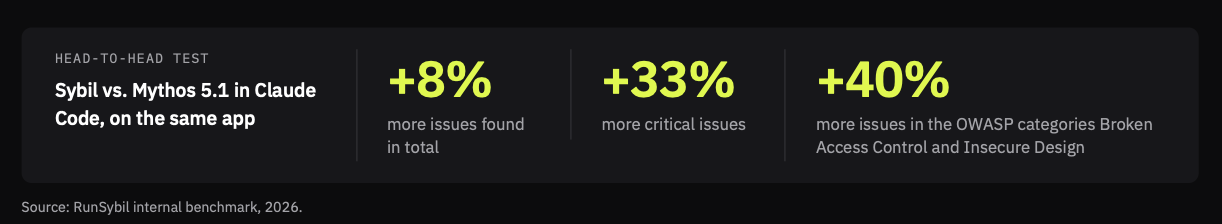
In our latest white-box benchmark, we tested Sybil and Mythos running in Claude Code against the same application. Sybil surfaced 8% more vulnerabilities than Mythos 5.1 in Claude Code. That includes 15% more critical- and high-severity vulnerabilities, and 33% more critical ones alone. In Broken Access Control and Insecure Design, our two largest industry-standard OWASP categories, Sybil surfaced 40% more vulnerabilities than Mythos 5.1.
What Sybil Adds That You Don’t Get With Mythos
- Live Testing: Most published frontier-model security results come from reading source code. Sybil doesn’t rely on source code. When it’s available, Sybil can use it as context to test your running application and prove the impact of each issue against it. Otherwise, you are left with hundreds to thousands of potential issues with no clear way to prioritize what needs to be fixed.
- Real Access, Safe Scope: Sybil tests with authenticated user roles and keeps every request inside your authorized scope.
- The Full Picture, Prioritized: Customers get confirmed Findings to fix first, plus Observations for valid, lower-impact issues and code-level Signals. You see everything Sybil sees, already sorted for your team.
- Continuity: Sybil remembers your application and keeps testing as your code changes. You don’t have to babysit agent sessions.
- Independently Reproduced: A separate check re-runs each exploit before you see it, to ensure every confirmed finding is real.
5. Resources
Add it all up and the real cost of building comes into focus. Any initial savings can easily get eaten by the time developers and security teams spend guiding agents, defining the scope of each evaluation, building and maintaining harnesses, triaging output, and context switching between all of that and their actual jobs. Then come the model and infrastructure costs, plus the need to hire or train people who understand both offensive security and how these models behave.
Organizations may well have the resources to build parts of this in-house. Building a scalable, consistently effective system across all five areas, and keeping it current, is a different level of investment entirely.
The goal is lowering cost per test without lowering quality. Using Sybil, teams cut wasted effort, not coverage.
And without the power and orchestration of thousands of agents running on a single engagement, any expected cost savings could turn into a far bigger expense: a security breach brought on because vulnerabilities went undiscovered or untriaged.
So, Build or Buy?
It depends on what you’re prepared to own. If your team can build and maintain all five pieces, and keep them sharp as models change, building can work. There’s also a middle ground: keep your own agents for specific jobs and rely on Sybil for continuous, validated testing across your attack surface.
What we’d caution against is assuming a few agents and a frontier model add up to a pentest. The model is one piece. The system around it is what finds, proves, and prioritizes the vulnerabilities that matter.
Ready to see how Sybil can help your organization? Get a live walkthrough.
Subscribe to RunSybil Blog
A weekly newsletter covering stories, techniques, guides and the latest product innovations coming.